Don't Ship Agent Skills Without Evals: Philipp Schmid's Testing Method and SkillsBench
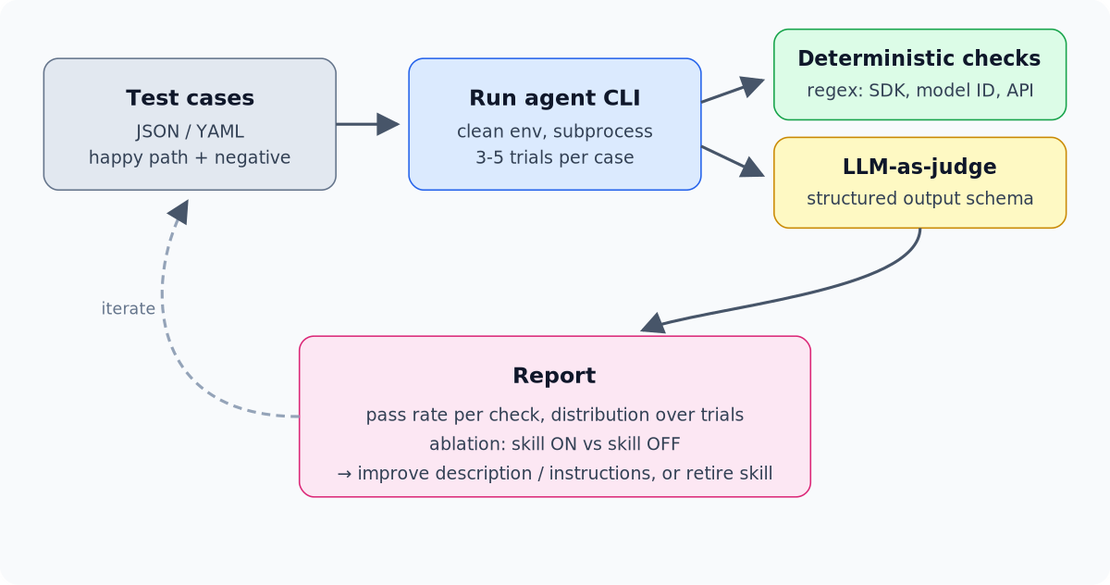
If you use a coding agent like Claude Code, Gemini CLI, or Codex, you eventually end up writing skills: Markdown files that hand the agent your team’s coding conventions, a specific SDK’s usage patterns, or a deployment procedure. The problem is that almost nobody tests them. We would never ship code without tests, yet skills, which directly change how an agent behaves, get shipped after a few manual runs and a gut-level “looks fine.”
Read More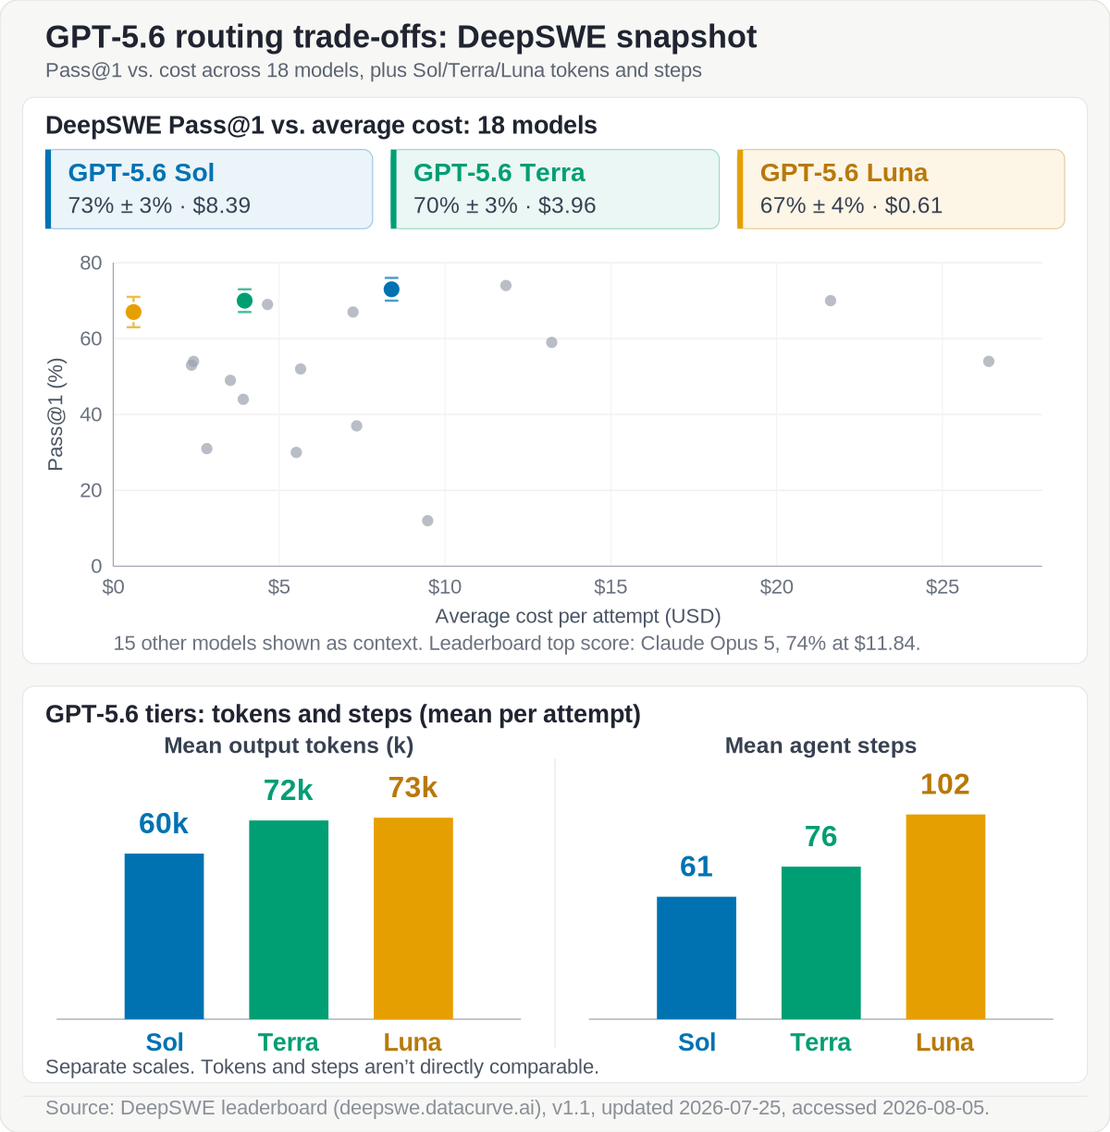
GPT-5.6 Sol, Terra, and Luna: A Model Routing Guide for Coding Agents
A claim like “Luna Max beats Terra High” circulates around GPT-5.6 discussions, and it does not hold up. Sol, Terra, and Luna are separate models, each a different capability tier. Max, high, xhigh, and ultra are settings within a given model that control how much reasoning time it uses and how many agents run in parallel. Collapsing a tier name and a settings name into one ranking compares two different axes as if they were one.
Read More
AI Self-Improvement Starts Outside the Model
An AI agent can improve its behavior across runs while its model weights stay unchanged. It can diagnose failures in execution traces, revise its prompts, memory, tools, or workflow, and retain changes that pass a separate evaluation. Persistent, tested changes distinguish harness improvement from simply making more attempts. Darwin Gödel Machine (DGM) changes a coding agent’s code; GEPA changes prompts; Reflexion changes the memory supplied to later trials. Each changes the system around a model rather than retraining that model. (DGM, GEPA, Reflexion)
Read More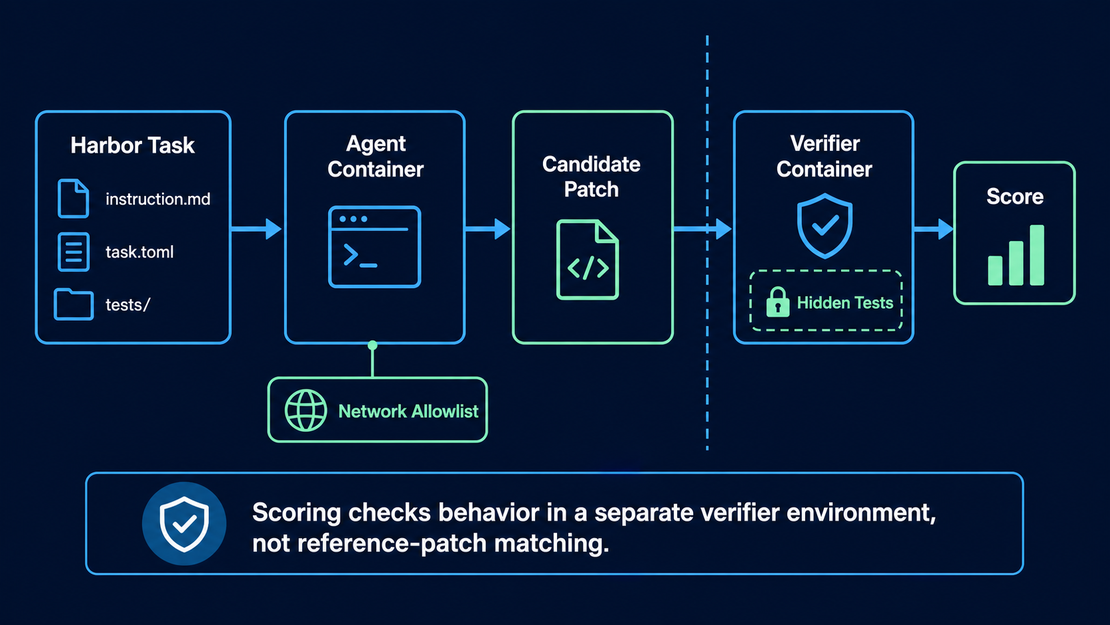
DeepSWE: A Benchmark for Long-Horizon Coding Agents
SWE-bench has been the default coding-agent leaderboard for a while, but it has well-known weaknesses. Most tasks come from existing public issues and PR patches, so a high score might partly reflect memorization. Most tasks are also single-file bug fixes, which is not representative of the multi-file, long-horizon work that a coding agent does in practice.
Read MoreTags
- A2a
- Act
- Agent
- Agent-Debate
- Agent-Finance
- Agent-Harness
- Agent-Skills
- Agentic-Payments
- Ai-Agent
- Ai-Agents
- Ai-Architecture
- Ai-Blockchain
- Ai-Research
- Ai-Search
- Ai-Security
- Akash
- Anthropic
- Apify
- Base
- Benchmark
- Besu
- Bitcoin
- Bittensor
- Block-Access-Lists
- Canton
- Capital-Markets
- Ccip
- Cctp
- Chainlink
- Circle
- Coding
- Coding-Agent
- Coinbase
- Commerce
- Competition
- Compliance
- Context-Engineering
- Cross-Chain
- Cryptography
- Daml
- Data
- Data-Enclosure
- Data-Licensing
- Decentralized-Compute
- Depin
- Dex
- Diffusion-Policy
- Distillation
- Eip
- Eip-2780
- Eip-3009
- Eip-8037
- Eip-8038
- Emergent-Behavior
- Ensemble
- Enterprise-Blockchain
- Epbs
- Erc-8001
- Erc-8004
- Erc-8041
- Erc-8126
- Erc-8183
- Erc-8196
- Erc-8226
- Ethereum
- Evals
- Evaluation
- Evm
- Execution-Client
- Fhe
- Fido2
- Fintech
- Gas
- Glamsterdam
- Goldman-Sachs
- Google-Cloud
- Gpt-5-6
- Groth16
- Harness
- Heloc
- Hermes-Agent
- Identity
- Imitation-Learning
- Institutional-Finance
- Kimi
- Knowledge-Management
- Kya
- Langfuse
- Langgraph
- Lerobot
- Llama-Cpp
- Llm
- Llm-Agents
- Llm-as-Judge
- Llm-Observability
- Local-Llm
- Maci
- Math
- Mcp
- Memory
- Metadata
- Mev
- Moa
- Model-Routing
- Moe
- Mpp
- Mtp
- Multi-Agent
- Observability
- Okf
- Onchain
- Open-Source
- Open-Standard
- Opik
- Orderbook
- Passkey
- Physical-Ai
- Platforms
- Post-Quantum-Cryptography
- Post-Training
- Privacy
- Prompt-Engineering
- Provenance
- Python
- Qbft
- Quant-Finance
- Quantum-Computing
- Qwen
- Rag
- Reasoning
- Reinforcement-Learning
- Render
- Reputation
- Retrieval
- Reverse-Kl
- Rl
- Robot-Learning
- Rwa
- Search-Agent
- Security
- Self-Improvement
- Semaphore
- Settlement
- Skills
- Small-Language-Model
- Smart-Contract
- Smart-Contracts
- Smolvla
- Snark
- Software
- Solidity
- Sp1
- Stablecoin
- Stigmergy
- Swe-Bench
- Tokenization
- Tracing
- Trading
- Tutorial
- Ucp
- Uncensored
- Usdc
- Validators
- Vla
- Voting
- Wallet
- Webauthn
- X402
- Ylds
- Zero-Knowledge
- Zk-Proof
- Zk-Rollup