AI
- Home /
- Categories /
- AI
Technology Moats in the AI Era
Building software and making money are different things I recently attended an AI conference. As I looked at the many products and demonstrations, one question kept coming back to me.
Read More
Data Enclosure and Platform Concentration in the AI Era
Data enclosure in the AI era is about platforms deciding who may reuse data, and for what purpose. Some end APIs; others supply selected AI companies under contract or charge for usage. These cases show access conditions being reorganized. They do not, by themselves, establish monopoly or unlawful conduct by any company.
Read More
Why did Anthropic publish its report on alleged Kimi-to-Claude routing?
If sensitive information was reaching Claude, why would Anthropic reveal the route? A model provider may gain more from limiting unauthorized use and alerting customers to a data-handling problem than from continuing to observe the inputs. Answering a competitor’s users consumes compute and may produce training material for that competitor. Publication also reaches users and enterprise buyers whom account bans alone cannot inform. These incentives explain why disclosure can make sense; they do not establish how Anthropic made its internal decision.
Read More
SwarmWorld: LLM Agents That Cooperate Without Talking, and Technology That Outlives Them
In SwarmWorld, agents can continue one another’s work without talking by observing persistent devices and changes to their shared environment. That shared world helped them build collections of technologies serving several functions, but did not guarantee the best individual device. The MIT researchers’ paper demonstrates collaboration through accumulating functional artifacts inside a specified simulator. It does not establish the invention of real materials or a universal advantage for real-world multi-agent systems.
Read More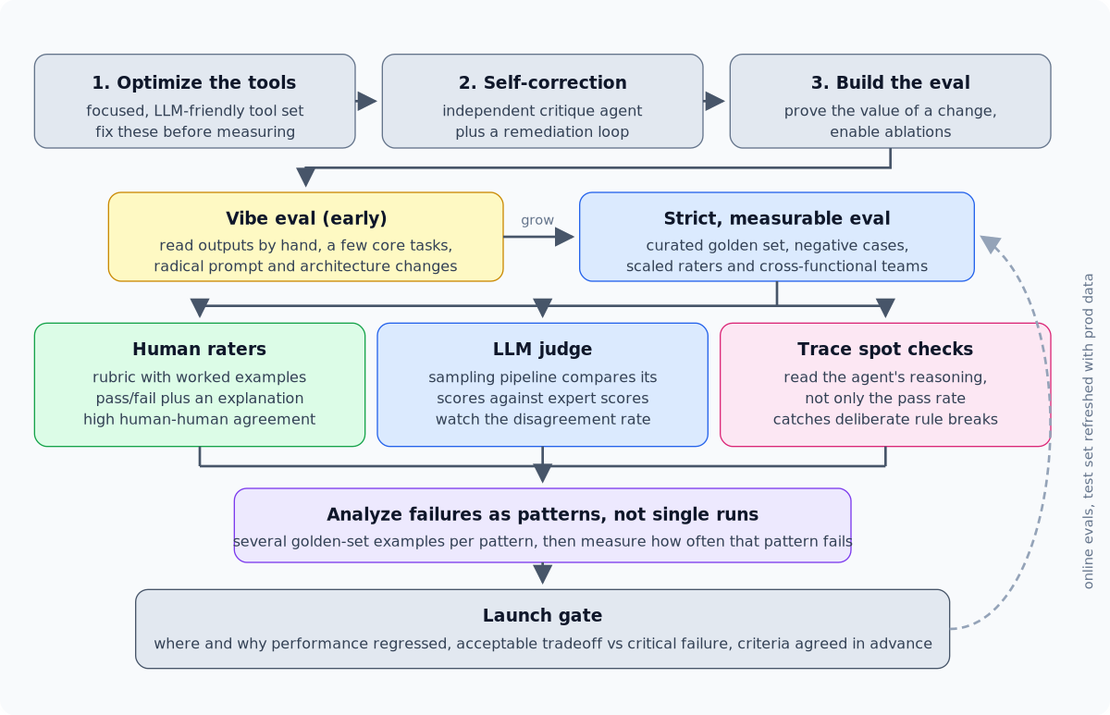
The Failure a Pass Rate Hides: How the YouTube Ads Team Runs Production Evals
The idea that a well-written prompt makes an agent behave holds up right until the demo ends. In production, the same prompt and the same input produce different results run to run. A case that passed yesterday fails today, and one that failed yesterday passes. Deciding whether that system is ready to ship takes measurement, not a feeling.
Read More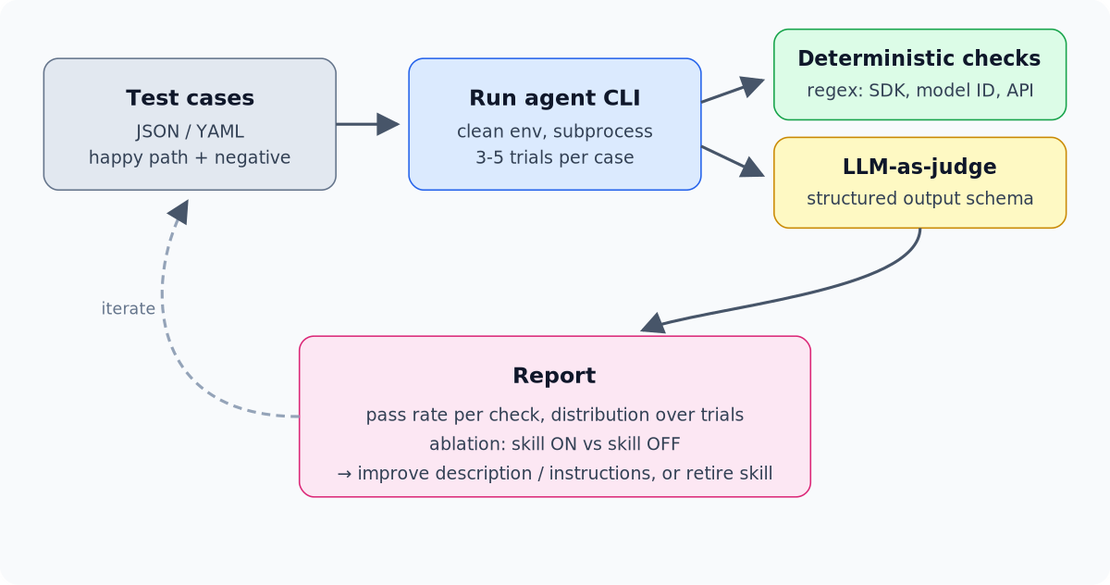
Don't Ship Agent Skills Without Evals: Philipp Schmid's Testing Method and SkillsBench
If you use a coding agent like Claude Code, Gemini CLI, or Codex, you eventually end up writing skills: Markdown files that hand the agent your team’s coding conventions, a specific SDK’s usage patterns, or a deployment procedure. The problem is that almost nobody tests them. We would never ship code without tests, yet skills, which directly change how an agent behaves, get shipped after a few manual runs and a gut-level “looks fine.”
Read More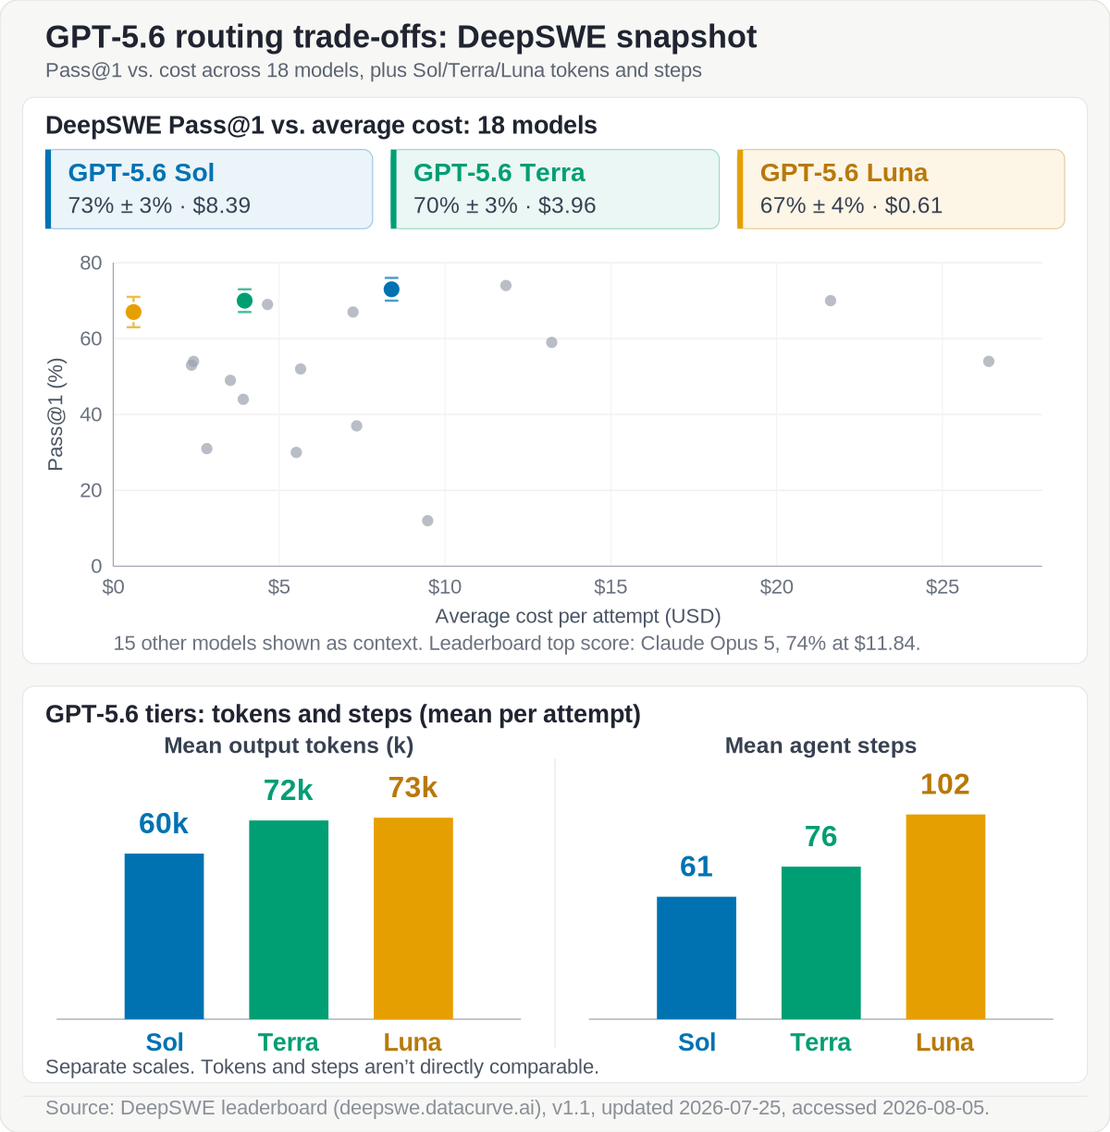
GPT-5.6 Sol, Terra, and Luna: A Model Routing Guide for Coding Agents
A claim like “Luna Max beats Terra High” circulates around GPT-5.6 discussions, and it does not hold up. Sol, Terra, and Luna are separate models, each a different capability tier. Max, high, xhigh, and ultra are settings within a given model that control how much reasoning time it uses and how many agents run in parallel. Collapsing a tier name and a settings name into one ranking compares two different axes as if they were one.
Read More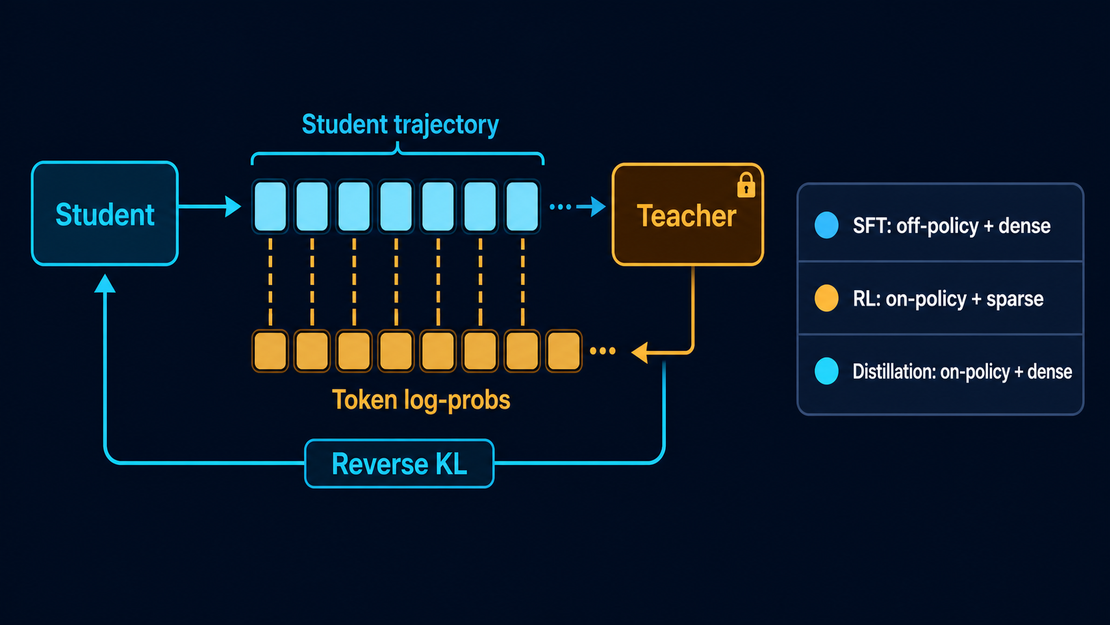
On-Policy Distillation: Closing the Gap Between RL and SFT
The two standard post-training methods each leave a gap. Supervised fine-tuning (SFT) has the student imitate sequences a teacher already produced, but training happens on states the student may never actually visit, so errors compound over long generations. Reinforcement learning (RL) samples from the student’s own rollouts, which fixes that mismatch, but the reward is usually a single bit or two per episode. A post Thinking Machines Lab published in October 2025 proposes combining the two: sample trajectories from the student, then have a strong teacher score every token in that trajectory.
Read More
AI Self-Improvement Starts Outside the Model
An AI agent can improve its behavior across runs while its model weights stay unchanged. It can diagnose failures in execution traces, revise its prompts, memory, tools, or workflow, and retain changes that pass a separate evaluation. Persistent, tested changes distinguish harness improvement from simply making more attempts. Darwin Gödel Machine (DGM) changes a coding agent’s code; GEPA changes prompts; Reflexion changes the memory supplied to later trials. Each changes the system around a model rather than retraining that model. (DGM, GEPA, Reflexion)
Read More
Hermes Agent v0.18: When a Self-Improving Agent Gets MoA
Nous Research’s open-source agent Hermes Agent shipped v0.18.0 on July 1, 2026. The release notes call it “The Judgment Release.” Reading this as a routine feature update misses the point. The official docs describe Hermes Agent as “the self-improving AI agent,” and the project is built around a loop that accumulates memory and skills the more it gets used. This post covers how that loop was refined in v0.18, and what role Mixture of Agents (MoA), now a first-class model choice in the same release, plays inside it.
Read More
TradingAgents: Reading the Paper and Code Behind an LLM Trading Desk
TradingAgents is a research framework in which several LLM agents analyze evidence, challenge a proposal, and produce a judgment about one instrument with supporting reports. In the current code, the risk team reviews the Trader’s proposal and the Portfolio Manager assigns the final rating. The paper’s high backtest returns do not establish that these ratings translate into live profits. The current evaluation code explicitly excludes order fills and an account cash ledger. Final decision, evaluation scope
Read More
Harness-1: Teaching Search Agents to Offload State
Search agents and the state problem A search agent is an AI system that answers a question by iterating through multiple searches. Unlike a one-shot retrieval lookup, it reads intermediate results, adjusts its search strategy, compares candidate documents, and checks whether specific claims are actually supported by what it found. Tasks like analyzing financial filings, tracing multi-hop facts across sources, or interpreting complex regulations need this kind of iterative work. A single query won’t get you there.
Read More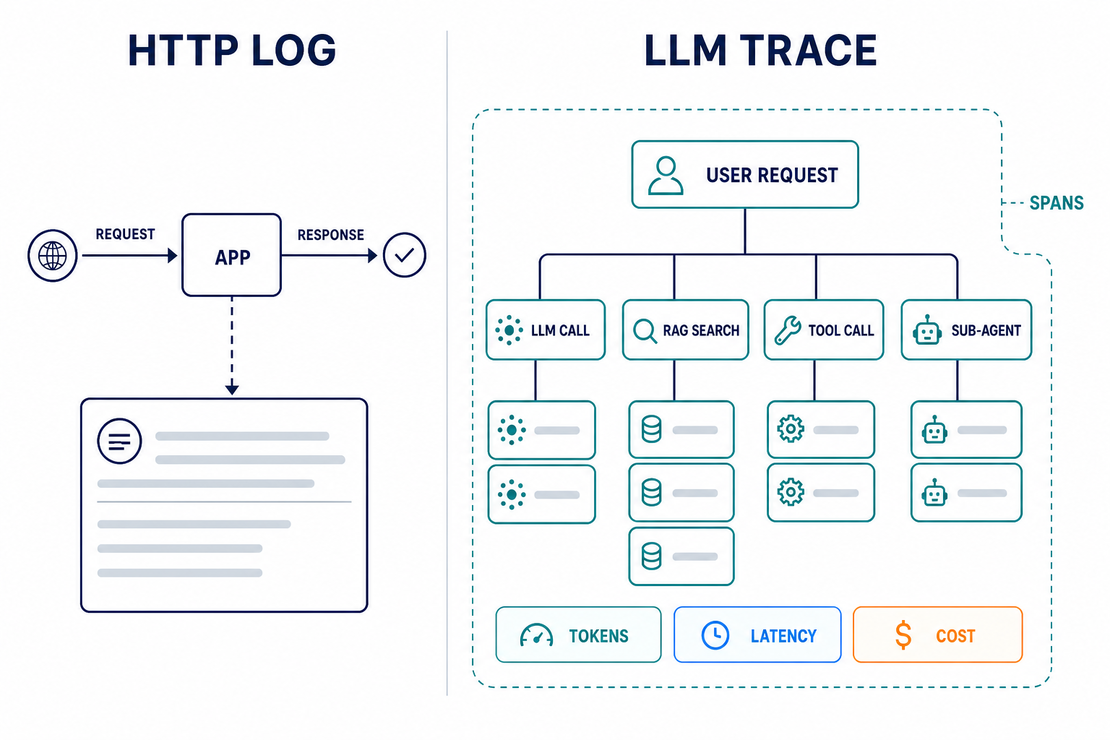
LLM Observability Without LangSmith: Five Open-Source Tools Compared
At some point in building LLM applications or agents, you need to know why a call failed, what the tool invocation looked like, or why the agent got stuck in a loop. LangSmith, LangChain’s commercial observability platform, has been the default answer for this: it covers trace visualization, prompt versioning, and evaluation in one place. Its usage-based pricing and cloud-hosted architecture are where teams start looking for alternatives. Traces carry raw user inputs and internal prompts, so shipping that data to an external SaaS is itself a problem for plenty of organizations.
Read More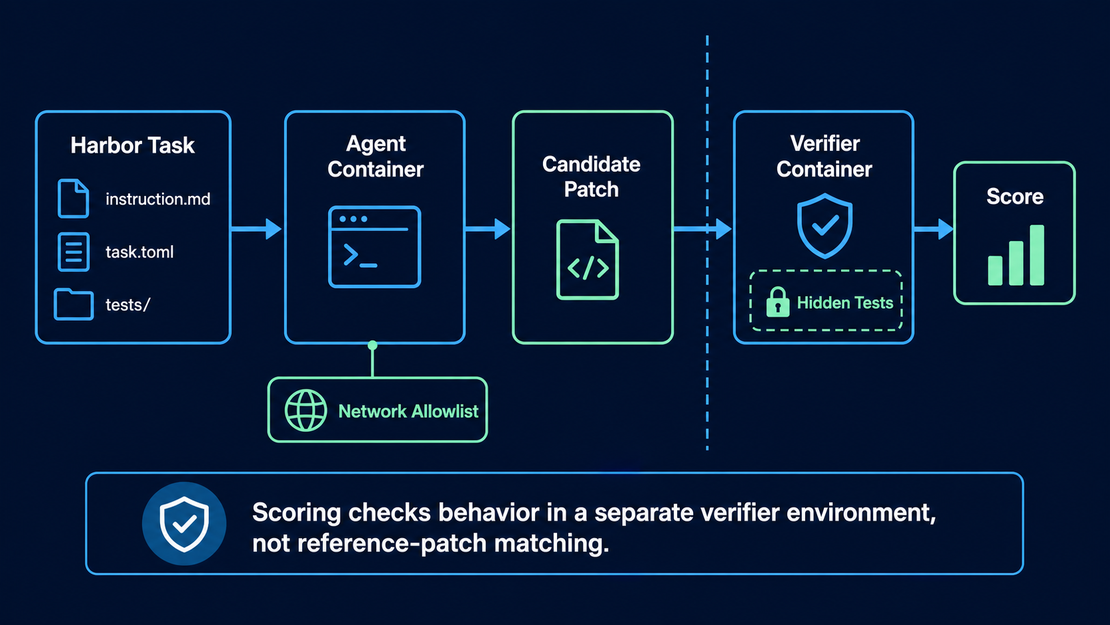
DeepSWE: A Benchmark for Long-Horizon Coding Agents
SWE-bench has been the default coding-agent leaderboard for a while, but it has well-known weaknesses. Most tasks come from existing public issues and PR patches, so a high score might partly reflect memorization. Most tasks are also single-file bug fixes, which is not representative of the multi-file, long-horizon work that a coding agent does in practice.
Read More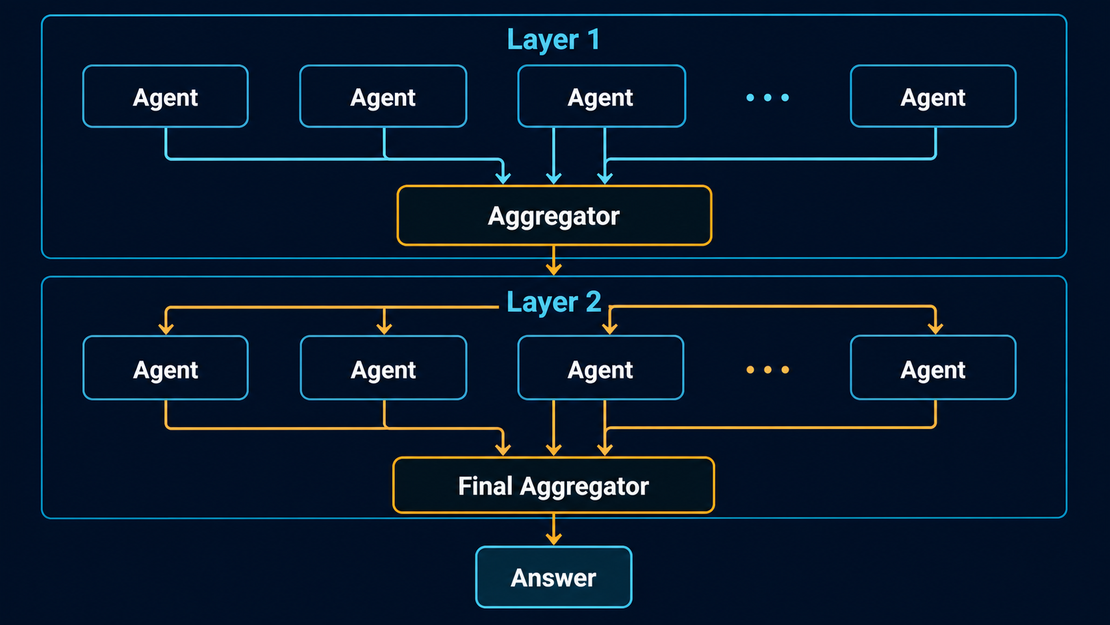
Mixture of Agents: How Layering Open-Source LLMs Beat GPT-4 Omni
Instead of scaling a single model up, you can stack multiple models in layers and have each one refine the previous layer’s output. Together AI’s research team formalized that approach in June 2024 as Mixture of Agents (MoA) in arXiv:2406.04692. Using only open-source models, their MoA configuration scored 65.1% on AlpacaEval 2.0, versus 57.5% for GPT-4 Omni.
Read More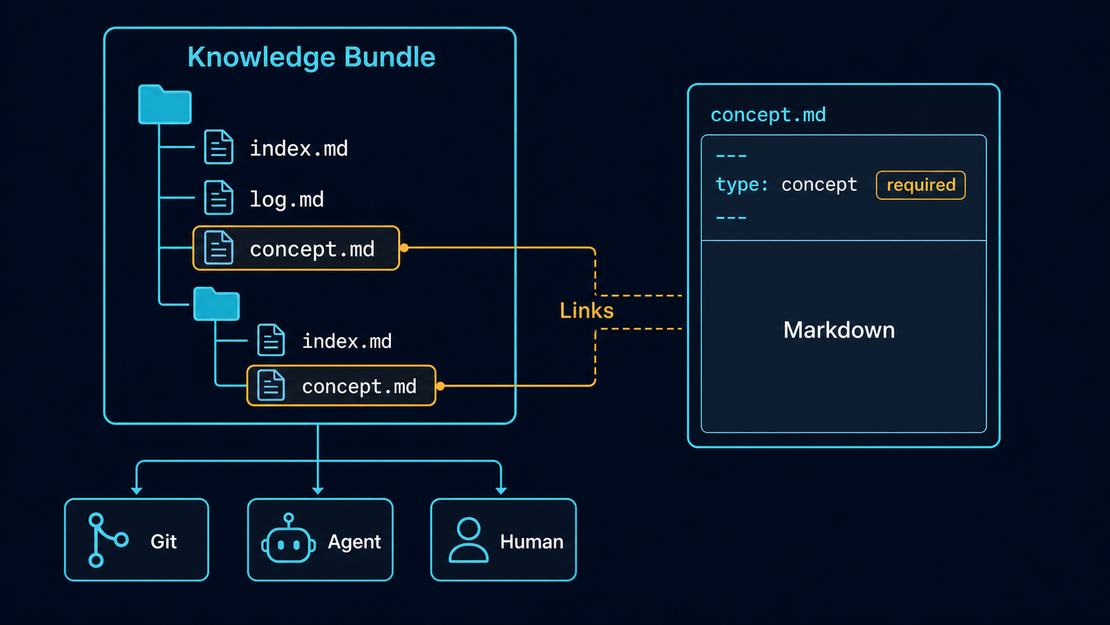
Open Knowledge Format: A Shared Vocabulary for Agent Knowledge
When AI agents fail in production, the model is often not the problem. The missing context is. Table schemas, metric definitions, runbooks, join paths between systems, and API deprecation notices are scattered across catalog vendors, internal wikis, code comments, and personal notes. Every agent developer solves the same context assembly problem from scratch.
Read More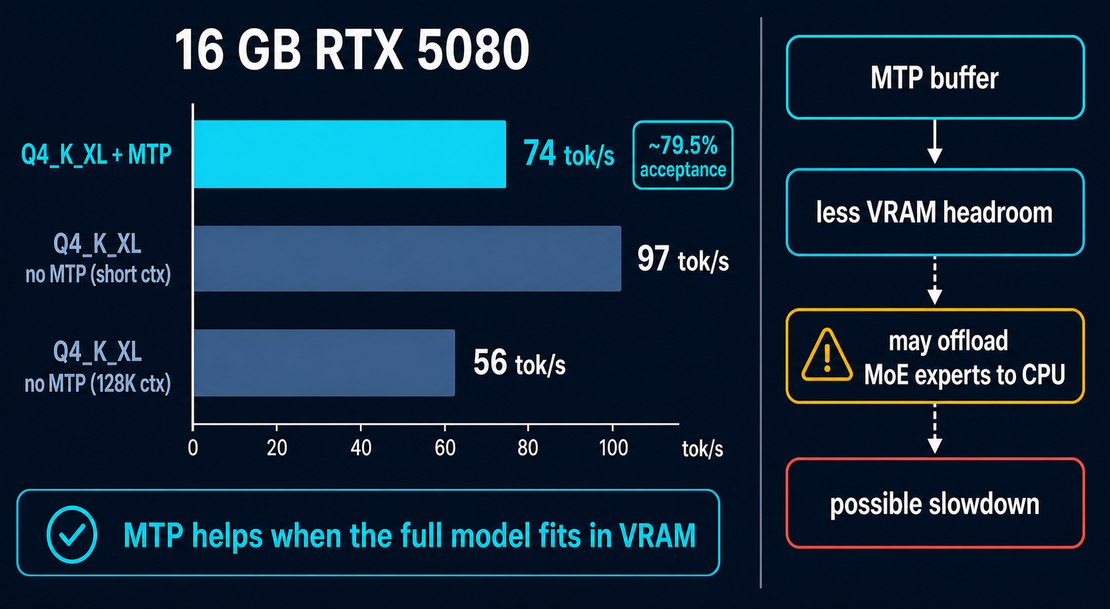
Qwen3.6-35B-A3B: Community Reviews, Uncensored Variants, and MTP Benchmarks
Alibaba released Qwen3.6-35B-A3B in April 2026: a 35B-parameter MoE model with around 3B active per token, a 262K native context, and an official SWE-bench score of 73.4%. Two months in, it’s the most widely tested 35B-class model in the local LLM community.
Read More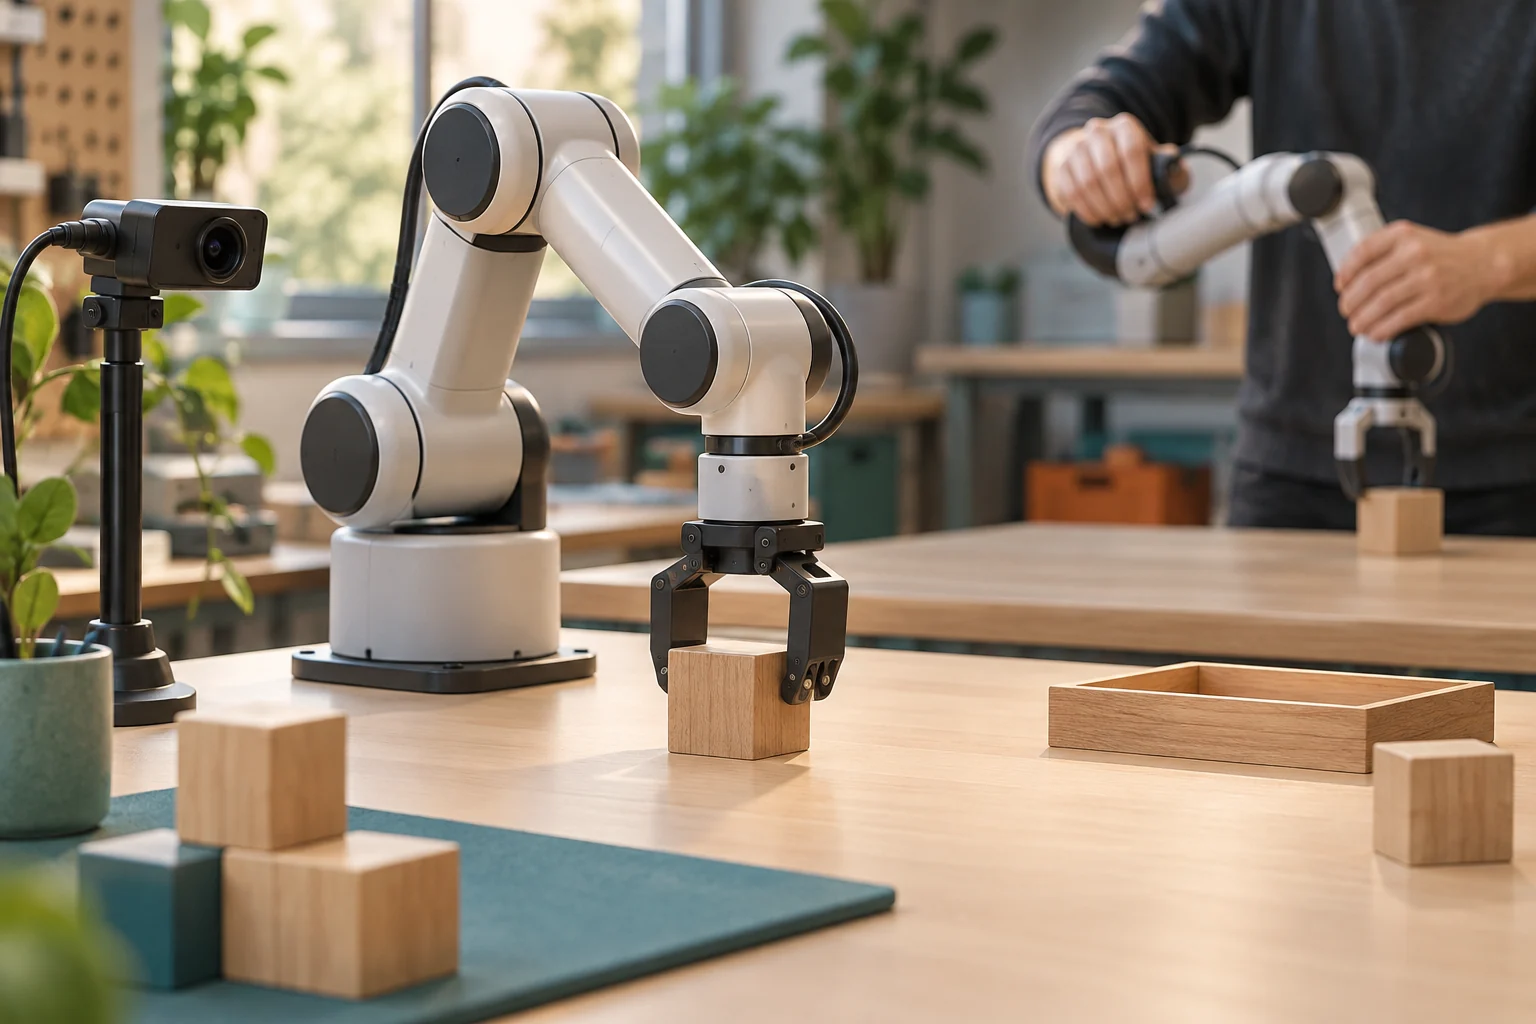
Robot Learning: A Tutorial (From Classical Robotics to Generalist Policies)
A practical way to start robot learning is to teleoperate one task, train an imitation policy such as ACT, and evaluate it on the same hardware under controlled conditions. Classical control handles joints and motion; the learned policy selects actions from observations. A VLA adds language instructions and pretraining, but calibration, data collection, and physical evaluation remain necessary. LeRobot’s official documentation also recommends ACT as a first policy.
Read More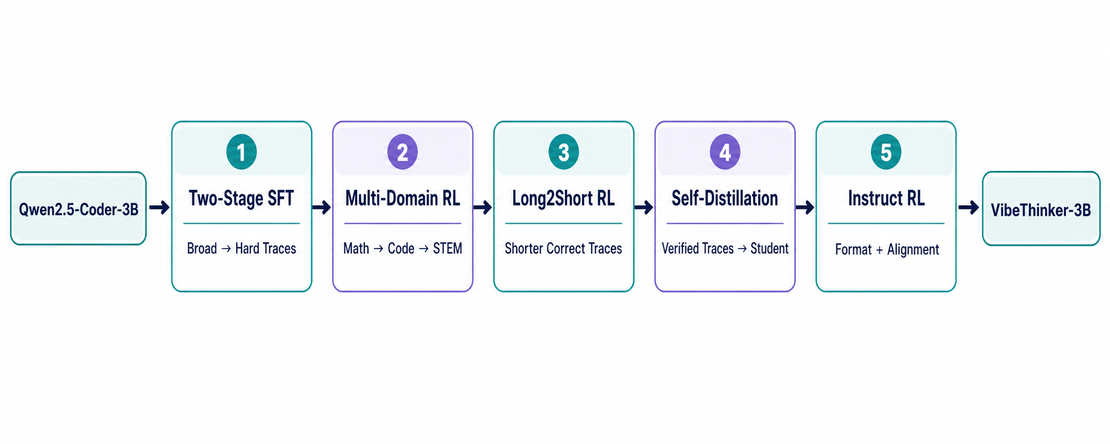
VibeThinker-3B: Packing Verifiable Reasoning into 3 Billion Parameters
“Small model beats big model” papers appear regularly. Usually the claim holds on a specific benchmark under specific conditions, not across the board. WeiboAI’s VibeThinker-3B, published June 15, 2026, follows a similar structure but draws a clearer boundary: the claim is not that a 3B model replaces a frontier generalist. The claim is that verifiable reasoning can be compressed into a small model, while open-domain knowledge and general dialogue still benefit from more parameters.
Read More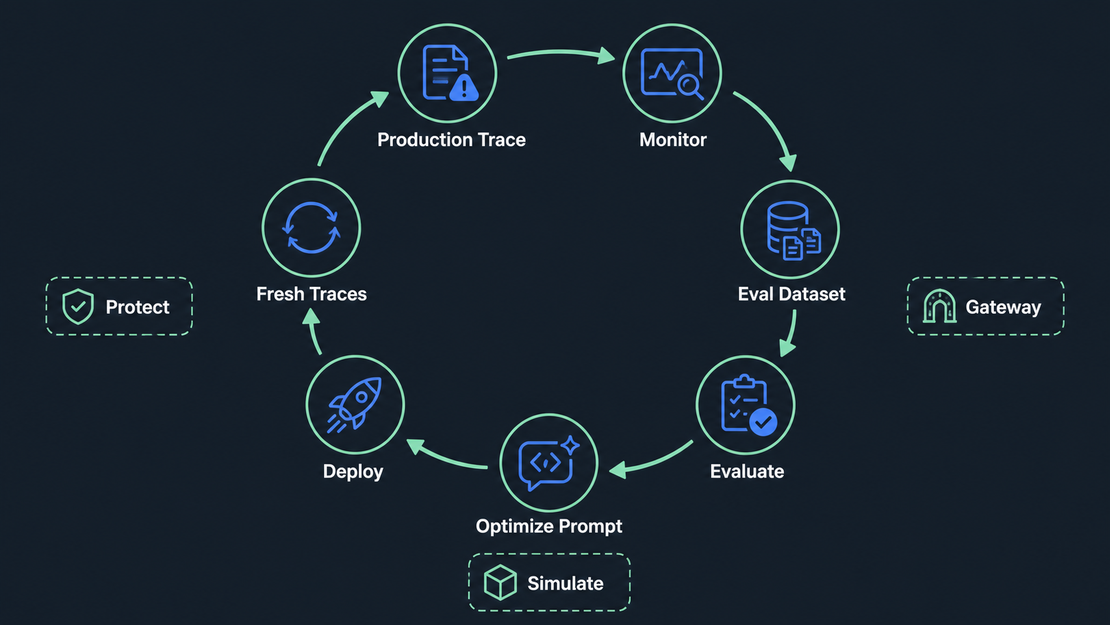
Future AGI: Evaluate, Observe, and Improve AI Agents in One Place
If you have shipped an AI agent, this will sound familiar. The demo runs fine. Then it hits production, the hallucinations start, and you can’t tell what went wrong or why. So you bolt on one tool for evals, another for tracing, another for guardrails. The real problem is that none of them talk to each other, so the loop you need to actually fix things never closes.
Read MoreTags
- A2a
- Act
- Agent
- Agent-Debate
- Agent-Finance
- Agent-Harness
- Agent-Skills
- Agentic-Payments
- Ai-Agent
- Ai-Agents
- Ai-Architecture
- Ai-Blockchain
- Ai-Research
- Ai-Search
- Ai-Security
- Akash
- Anthropic
- Apify
- Base
- Benchmark
- Besu
- Bitcoin
- Bittensor
- Block-Access-Lists
- Canton
- Capital-Markets
- Ccip
- Cctp
- Chainlink
- Circle
- Coding
- Coding-Agent
- Coinbase
- Commerce
- Competition
- Compliance
- Context-Engineering
- Cross-Chain
- Cryptography
- Daml
- Data
- Data-Enclosure
- Data-Licensing
- Decentralized-Compute
- Depin
- Dex
- Diffusion-Policy
- Distillation
- Eip
- Eip-2780
- Eip-3009
- Eip-8037
- Eip-8038
- Emergent-Behavior
- Ensemble
- Enterprise-Blockchain
- Epbs
- Erc-8001
- Erc-8004
- Erc-8041
- Erc-8126
- Erc-8183
- Erc-8196
- Erc-8226
- Ethereum
- Evals
- Evaluation
- Evm
- Execution-Client
- Fhe
- Fido2
- Fintech
- Gas
- Glamsterdam
- Goldman-Sachs
- Google-Cloud
- Gpt-5-6
- Groth16
- Harness
- Heloc
- Hermes-Agent
- Identity
- Imitation-Learning
- Institutional-Finance
- Kimi
- Knowledge-Management
- Kya
- Langfuse
- Langgraph
- Lerobot
- Llama-Cpp
- Llm
- Llm-Agents
- Llm-as-Judge
- Llm-Observability
- Local-Llm
- Maci
- Math
- Mcp
- Memory
- Metadata
- Mev
- Moa
- Model-Routing
- Moe
- Mpp
- Mtp
- Multi-Agent
- Observability
- Okf
- Onchain
- Open-Source
- Open-Standard
- Opik
- Orderbook
- Passkey
- Physical-Ai
- Platforms
- Post-Quantum-Cryptography
- Post-Training
- Privacy
- Prompt-Engineering
- Provenance
- Python
- Qbft
- Quant-Finance
- Quantum-Computing
- Qwen
- Rag
- Reasoning
- Reinforcement-Learning
- Render
- Reputation
- Retrieval
- Reverse-Kl
- Rl
- Robot-Learning
- Rwa
- Search-Agent
- Security
- Self-Improvement
- Semaphore
- Settlement
- Skills
- Small-Language-Model
- Smart-Contract
- Smart-Contracts
- Smolvla
- Snark
- Software
- Solidity
- Sp1
- Stablecoin
- Stigmergy
- Swe-Bench
- Tokenization
- Tracing
- Trading
- Tutorial
- Ucp
- Uncensored
- Usdc
- Validators
- Vla
- Voting
- Wallet
- Webauthn
- X402
- Ylds
- Zero-Knowledge
- Zk-Proof
- Zk-Rollup