TradingAgents: Reading the Paper and Code Behind an LLM Trading Desk
Table of Contents
TradingAgents is a research framework in which several LLM agents analyze evidence, challenge a proposal, and produce a judgment about one instrument with supporting reports. In the current code, the risk team reviews the Trader’s proposal and the Portfolio Manager assigns the final rating. The paper’s high backtest returns do not establish that these ratings translate into live profits. The current evaluation code explicitly excludes order fills and an account cash ledger. Final decision, evaluation scope
Separating the research idea from the runnable implementation clarifies its purpose. The paper proposes a decision process built from specialist roles and debate, then reports a historical simulation. The public implementation runs that process and preserves intermediate reports and the final judgment. This article uses paper v7 and the latest release, v0.6.0, checked on October 16, 2026 (KST); code links are pinned to commit 1394a3f. The release was published on October 3, 2026 at 21:30 UTC. Paper, release
The result is a rating and a set of reports
A run takes an instrument and an analysis date. TradingAgentsGraph.propagate() returns the full state and a final rating. The five ratings are Buy, Overweight, Hold, Underweight, and Sell. When the model supports structured output, the Portfolio Manager’s typed rating is used directly. The text fallback reads an explicit Rating: label. An unreadable rating produces REVIEW, keeping a failure to decide from being recorded as a Hold that nobody chose. Return contract, rating parser
The Trader’s Buy/Hold/Sell action is an intermediate proposal. It receives the research plan and, when the market analyst is selected, price information from the technical report. It proposes entry and stop prices and position sizing. Price fields must be absolute prices in the instrument’s quote currency; the prompt allows their omission when a number cannot be stated. The proposal still awaits the Portfolio Manager’s judgment after the risk debate. Trader, Portfolio Manager
save_reports() writes the stage reports, combined Markdown, and complete_report.html. Reports also record the analysis date, version, models and providers, selected analysts, debate rounds, and data vendors. This helps a reader revisit the evidence and locate a failed stage. A readable explanation alone does not verify the underlying data or establish profitability. Report API, release
The paper and README describe simulated execution, but the current graph returns state and a rating. In particular, backtest.py defines itself as a decision-quality evaluator without quantities, fill prices, or a cash ledger. Running analysis, simulating a portfolio, and placing broker orders are distinct capabilities. Paper §5, current evaluator
Shared reports feed two debates
TradingAgents separates evidence gathering from judgment. Four analysts write specialist reports, and bullish and bearish researchers argue over the same material. The Research Manager forms an investment plan, the Trader turns it into a transaction proposal, and three risk perspectives review it again. Paper §§3-4, graph construction
| Stage | Inputs and responsibility | Output passed forward |
|---|---|---|
| Analysts | Separate analyses of prices and indicators, social sentiment, news and macro data, and company financials | Specialist reports |
| Bull / Bear Researcher | Exchange arguments for and against an investment using those reports | Debate history |
| Research Manager | Weigh the competing arguments | Investment plan |
| Trader | Read the plan, selected market report, and supplied portfolio context | Transaction proposal |
| Risk debate | Review the proposal from aggressive, conservative, and neutral perspectives | Risk debate history |
| Portfolio Manager | Combine the plan, proposal, risk discussion, and lessons from previous decisions | Final rating and rationale |
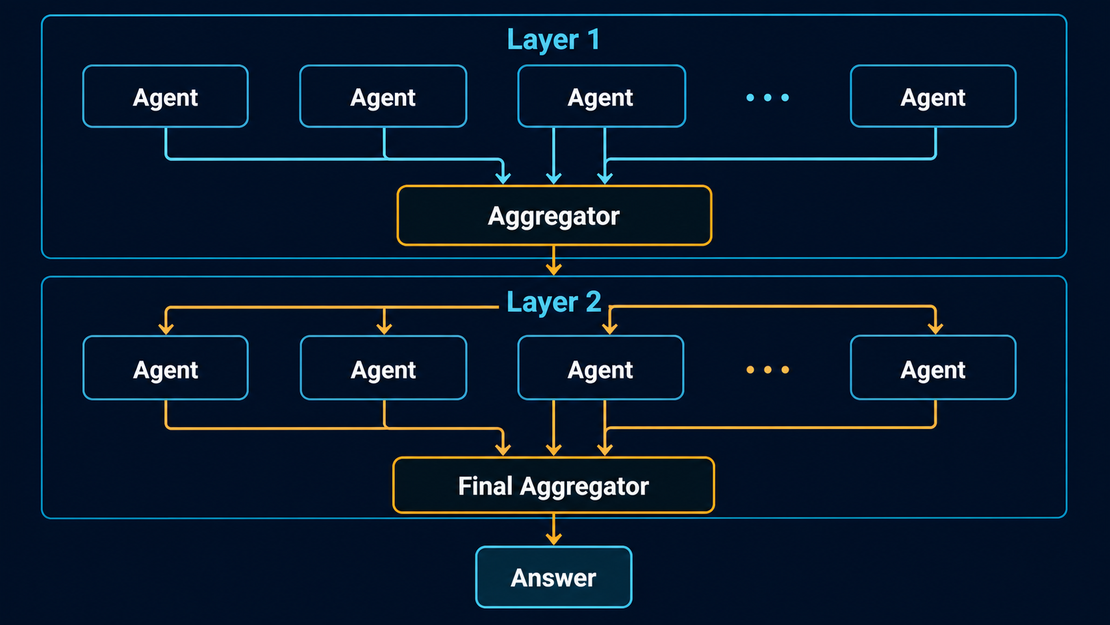
The current implementation runs selected analysts in parallel. Each analyst subgraph has private messages and tools and returns only its report. The bullish/bearish debate starts after every report and the concurrently running memory step have finished. The subsequent decision stages follow a defined sequence. Multiple agents do not make the entire pipeline concurrent. Parallel execution and join
Reports, investment plans, and debate histories occupy separate state fields. The paper’s structured communication does not mean every sentence becomes a number or a strict schema. Agents read the reports they need from shared state, debate in natural language, and save that discussion in the state too. This reduces dependence on one growing conversation. It still permits several roles to repeat the same bad evidence. Role separation alone does not create independent verification. Paper §4, implementation
Debates stop at configured limits. By default, the bullish and bearish researchers each speak once, and each of the three risk perspectives speaks once. The routers hand control to the managers at 2 × max_debate_rounds and 3 × max_risk_discuss_rounds. An analyst reaching the default 20 tool-call rounds is asked to finish a report from the evidence it has. That cap counts rounds, rather than 20 individual tool calls across the run. Debate limits, tool-loop limit
Model allocation is another experimental condition. Current defaults name gpt-6-luna for quick_think_llm and gpt-6-sol for deep_think_llm. Analysts, researchers, the Trader, and risk debaters use the quick model; the two managers use the deep model. Each tier can have its own provider. These are repository defaults, not a reproduction of the GPT-4o-family and o1-preview arrangement discussed in paper §4.3. Defaults, role allocation, paper §4.3
Availability time matters more than the period a datum describes
Historical analysis needs more than data about a past period. The information must already have been public when the decision was made. A fiscal year can end before its financial report is filed. A later restatement can also reveal information unavailable at the original decision. The current implementation handles these timing problems by data type. Date rules, SEC EDGAR implementation
| Data | Current handling | Remaining condition |
|---|---|---|
| SEC EDGAR statements | Select figures filed by the analysis date, using restatements available then | Limited to SEC filers and available filing history |
| Current Yahoo/Alpha Vantage profiles, statements without filing dates, and insider trades | Withhold them from historical runs | Present-day values cannot fill the gaps |
| News, Reddit, and StockTwits | Filter publication timestamps to the analysis window; omit undated historical items | A recent feed is not a complete historical archive |
| FRED macro series | Pin both the observation window and the historical data vintage | Constrain use of later revisions |
| Polymarket probabilities | Withhold them on historical runs because a historical vintage is unavailable | Current odds cannot stand in for past forecasts |
The table follows the shared date rules, SEC EDGAR, FRED, and Polymarket implementations. The default statement vendor chain is sec_edgar,yfinance. The README says machine-readable EDGAR filings begin in 2009, with potentially sparse early coverage. This does not promise equally deep historical statements for every non-US market. Configuration, coverage
An empty news search also has two meanings. A feed that cannot reach the requested period has failed to provide its history; it has not established that no news existed. The shared coverage_gap() reports that distinction, and the router tries alternatives within the configured vendor chain. Date filters cannot recover an original archive that a source never supplied. Coverage gaps, vendor routing
These guards still have a time-resolution limit. The publication filter admits items before midnight UTC following the analysis date. Reading that bound literally, it includes the entire UTC analysis day, which does not establish what was known before the market opened. An opening-time strategy therefore needs an explicit decision timestamp, exchange timezone, and a rule for fills possible after that timestamp. Timestamp comparison
Tool-date constraints and model knowledge are separate issues. A model trained on historical news and prices could know an event’s outcome even when its tools supply no later data. Contamination has not been established for this experiment. Equally, a date filter alone does not demonstrate that model knowledge could not affect the result.
The paper reports a bounded simulation
Paper v7 evaluates January 1 through March 29, 2024. Section 5 describes several large technology stocks and inputs spanning prices, news, social data, financials, and 60 technical indicators per asset. Table 1 reports AAPL, GOOGL, and AMZN. Its baselines are Buy and Hold, MACD, KDJ+RSI, ZMR, and SMA. Those three table entries should not be mistaken for the whole dataset. Paper §5 and Table 1
| Ticker | Cumulative return CR | Reported annualized return ARR | Sharpe Ratio | Maximum drawdown MDD |
|---|---|---|---|---|
| AAPL | 26.62% | 30.5% | 8.21 | 0.91% |
| GOOGL | 24.36% | 27.58% | 6.39 | 1.69% |
| AMZN | 23.21% | 24.90% | 5.60 | 2.11% |
These are author-reported values from the TradingAgents row of Table 1. The highest baseline cumulative returns in the same table are 2.05%, 7.78%, and 17.1%, respectively. The reported gaps are large, but that comparison does not isolate the contribution of debate or establish performance in other market periods. Table 1
The figures also need a consistency check. Appendix S1.2 defines annualized return as (ending value / starting value)^(1/N) - 1, with N measured in years. Assuming exactly 0.25 years, AAPL’s 26.62% cumulative return would give about 157.05%, rather than the table’s 30.5%. This is a check on the stated period, formula, and table, not a replacement performance estimate. The discrepancy needs explanation before the ARR column can be read as an expected annual return. Appendix S1.2
The Sharpe Ratio of 8.21 also belongs beside the short observation window. The authors acknowledge that the highest value exceeds their empirical expectations and attribute it to few pullbacks during that period. The same footnote says 11 LLM calls and more than 20 tool calls per prediction limited the experiment to three months. That is the paper’s workload, not a measurement of current-version calls or cost per run. Paper §6.1.2 footnote
A live-performance claim would require an evaluation that accounts for fees, slippage, fill timing, and latency. The paper’s experimental description and metric definitions do not provide enough detail to reproduce those conditions confidently. Its conclusion places live deployment and expanded real-time feeds in future work. The table therefore supports a comparison within a particular experiment, rather than current live-trading capability or net profitability after costs. Paper §§5, 7
Conditions to fix before another evaluation
The current backtest runs the pipeline over a ticker/date grid and summarizes sample counts, directional hit rates, and mean benchmark-relative returns by rating. The default outcome window is five trading days after the analysis date. Hold has no directional hit rate, and REVIEW is unscored. Cells are independent: even a supplied portfolio is the same standing book for every cell, with no balance carried forward from earlier trades. This is not a reproduction engine for the paper’s portfolio returns. Evaluator, default window
Memory changes the next decision’s inputs as well. Alongside the analysts, the memory step settles decisions whose holding periods have elapsed, computes the instrument return and alpha against its regional benchmark, and generates a short reflection. The Portfolio Manager reads recent decisions for the same ticker and lessons from other tickers. Historical runs receive only entries whose outcomes were known by their analysis date. This updates prompt context; it neither trains model weights nor demonstrates that the reflections improve generalization. Memory step, historical context filter, outcome calculation
This example selects only the market and news analysts and reads the final rating and rationale. Running it calls LLM and data APIs and writes local records; save_reports() saves the reports. Official usage
from tradingagents.default_config import DEFAULT_CONFIG
from tradingagents.graph.trading_graph import TradingAgentsGraph

config = DEFAULT_CONFIG.copy()
config["max_debate_rounds"] = 1
ta = TradingAgentsGraph(selected_analysts=["market", "news"], config=config)
state, rating = ta.propagate("AAPL", "2026-09-01")
print(rating)
print(state["final_trade_decision"])
ta.save_reports(state, "AAPL")
Choosing the same date does not fix the experiment. A useful comparison should preserve the code SHA, exact model IDs and providers, reasoning and sampling settings, selected analysts, debate and tool limits, original data and publication times, and initial memory state. The report’s run_settings captures some of these conditions, but it does not archive every source feed. The evaluator also states that it uses one model sample per cell. Repeated-run variation and missing or failed cells belong alongside any reported average. Recorded settings, evaluation limitations
Costs depend on models, tool loops, debate length, retries, and reflections on previous decisions. Parallel analysts can reduce elapsed time while every call still incurs its own cost. The paper’s call count cannot be converted into a current dollar bill without measuring a run using the selected models. Productive research questions are whether the system improves on a single agent given the same evidence and budget, and which objections actually change its final judgment. Answering them requires controlled evaluation as well as readable reports.
Further reading
- Full paper v7: role specialization, experimental methods, tables, and metric definitions together.
- Current evaluator source: the explicit boundary between decision scoring and portfolio simulation.
- Shared date rules: analysis dates, publication timestamps, and coverage gaps in code.
References
- TradingAgents: Multi-Agents LLM Financial Trading Framework v7: Yijia Xiao et al., revised June 3, 2025; accessed October 16, 2026 KST.
- Pinned TauricResearch/TradingAgents source: Apache-2.0, commit
1394a3f72aa4393e1a98f51b382434c4b4c2d972; accessed October 16, 2026 KST. - TradingAgents v0.6.0: official release, published October 3, 2026 UTC; accessed October 16, 2026 KST.